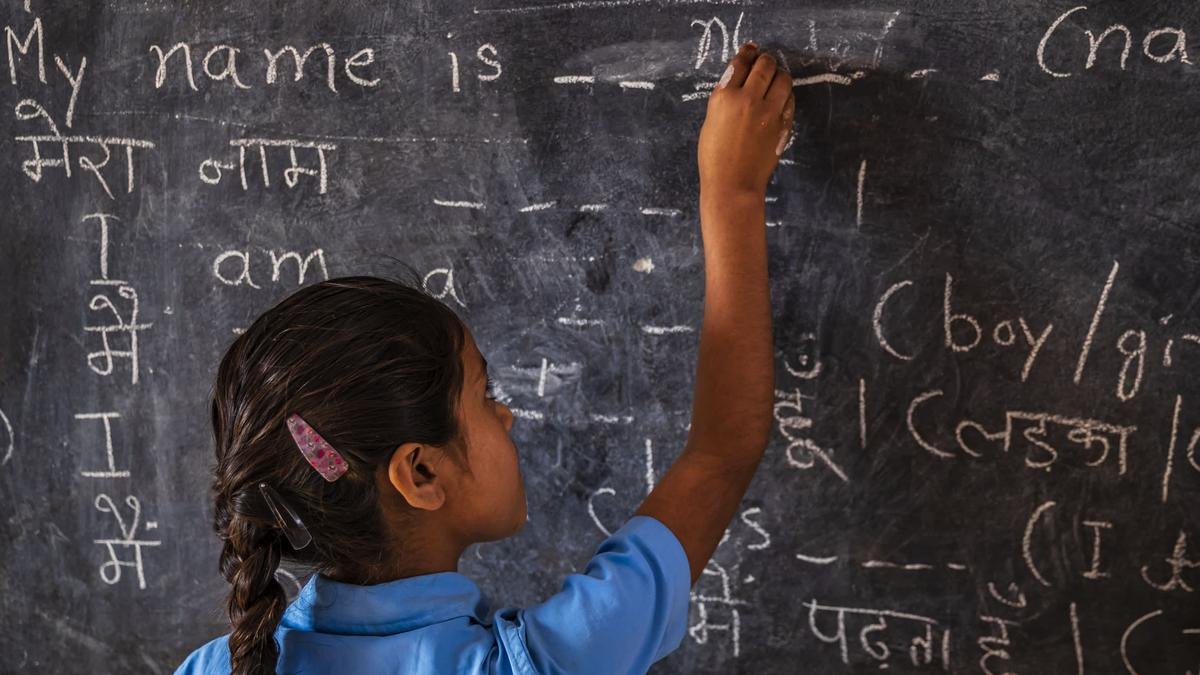
Source: The Hindu
Introduction
The rapid evolution of artificial intelligence has revolutionized how humanity interacts with technology, yet a major barrier remains for multilingual populations. Across the globe, sophisticated language models struggle to comprehend the vast array of regional dialects and local vernaculars that define everyday human communication. Teaching AI to speak India represents a monumental undertaking, as developers race to bridge the digital divide for one of the world's most linguistically diverse nations. Without comprehensive datasets reflecting these unique idioms, millions of citizens risk being excluded from the benefits of modern technological advancement.
Traditional automated systems have long favored globally dominant tongues, leaving regional dialects entirely unsupported or poorly translated. To counter this digital exclusion, dedicated researchers are embarking on extensive field expeditions to capture authentic speech patterns directly from native speakers. By gathering these vital audio samples, technology creators hope to build inclusive platforms capable of understanding complex regional nuances. This ambitious endeavor highlights the critical intersection between advanced computing and cultural preservation in the modern era.
What Happened
Specialized researchers operating within the academic ecosystem of IIT Madras are actively spearheading a nationwide initiative. Affiliated with the pioneering AI4Bharat initiative, these teams are traveling across the geographical expanse of India to document spoken communication firsthand. Their primary mission involves capturing diverse human voices in order to build robust computational frameworks that recognize regional speech. Through these rigorous documentation efforts, developers are actively teaching artificial intelligence how to process and interpret the country's incredible linguistic richness.
Rather than relying solely on existing digital text corpora, the expedition focuses heavily on gathering authentic verbal data from the ground level. Investigators record everyday conversations, oral traditions, and distinct phrasing across various communities to ensure the resulting datasets are thoroughly representative. This meticulous collection process forms the bedrock for training next-generation machine learning models that can successfully bridge communication gaps. By focusing on localized speech acquisition, the project aims to overcome the longstanding limitations of mainstream natural language processing software.
Background
Artificial intelligence systems are widely recognized for their ability to execute complex digital tasks, including conversational interactions, automated translation, and instant question answering. However, these powerful capabilities remain fundamentally dependent upon the availability of comprehensive linguistic training data. When automated software lacks exposure to specific regional dialects, its performance degrades significantly, resulting in communication failures for non-standardized speakers. India presents a particularly unique challenge due to its vast tapestry of distinct languages and localized ways of speaking.
Prior to these targeted field efforts, mainstream machine learning models frequently overlooked smaller or geographically isolated linguistic groups. This systemic oversight created a technological disadvantage for populations who do not converse in globally dominant languages. The work conducted by AI4Bharat directly addresses this historical imbalance by prioritizing the documentation of neglected dialects. Recognizing that computational tools must adapt to human diversity rather than forcing uniformity, the research team established a systematic approach to language preservation.
Key Details
The ongoing initiative relies on direct fieldwork to capture authentic linguistic data from various regions throughout the country. Researchers associated with AI4Bharat are physically moving across different territories to record human voices and archive endangered dialects. The core objective of this data gathering is to instruct advanced artificial intelligence systems on how to properly comprehend India's multifaceted linguistic landscape. Every collected audio sample serves as a vital building block for creating more inclusive conversational interfaces and translation tools.
| Project Element | Operational Details |
|---|---|
| Lead Institution | IIT Madras |
| Research Group | AI4Bharat |
| Core Activity | Collecting voices and preserving dialects |
| Primary Objective | Teaching AI to understand Indian linguistic diversity |
Impact
Successful execution of this language preservation and technological training initiative carries profound implications for digital accessibility. By ensuring that artificial intelligence can comprehend local vernaculars, developers are laying the groundwork for truly inclusive digital services. Citizens who previously faced barriers when interacting with automated systems will soon be able to utilize technology in their preferred native dialects. Furthermore, this large-scale audio archiving effort safeguards unique cultural expressions that might otherwise fade away in an increasingly digitized world.
Bridging the linguistic gap in machine learning also democratizes access to essential information, education, and government resources delivered through digital portals. When automated assistants and translation applications master regional speech, commerce and communication become frictionless for millions of additional users. The integration of local dialects into advanced computational models ultimately transforms technology from an exclusive utility into an accessible universal tool. This paradigm shift underscores the growing importance of community-driven data collection in shaping the future of global technology.
What Happens Next
The research teams continue their extensive travels across various regions to expand their growing repositories of audio data and linguistic archives. As additional voice samples are processed, developers will integrate these insights into training frameworks designed to refine machine learning algorithms. The ultimate trajectory of the initiative points toward the continuous enhancement of AI comprehension capabilities across an even broader spectrum of regional dialects. Through sustained fieldwork and technical refinement, the project moves steadily closer to achieving comprehensive linguistic representation for all speakers.


